Backup & Disaster Recovery Checklist 2026
Published:
A strong backup and disaster recovery checklist should test isolation, scope, retention, restore evidence, recovery objectives, dependency sequencing, ownership, and continuity planning—not just whether backup jobs completed.
Verizon’s 2025 DBIR reported that ransomware was present in 44% of breaches, while the Canadian Centre for Cyber Security identifies ransomware as the top cybercrime threat to Canada’s critical infrastructure. Those findings are why this checklist focuses on restore evidence, isolation, credential separation, and recovery sequencing instead of treating successful backup jobs as proof of recoverability.
How to use this checklist
This checklist is most useful when it is treated as a test of recovery credibility, not just backup administration. The key question is not whether a control exists somewhere in the environment. It is whether the business could explain, with confidence, how recovery would work under real pressure.
Strong answers usually include evidence, owners, realistic timing assumptions, and a clear understanding of dependencies. Weak answers usually rely on job-success notifications, vendor reassurance, or undocumented institutional knowledge. The difference between those two states becomes painfully obvious only when recovery is already urgent, which is why it is better to challenge the assumptions now.
1. Backup coverage checklist
Review whether:
- critical systems and data are actually included in backups
- retention periods match operational and legal needs
- cloud workloads are included where necessary
- encryption and access control are appropriate
- backup scope reflects current business reality, not last year’s environment
Coverage gaps are often created by change, not neglect. A new SaaS workload is added. A line-of-business platform becomes critical. A team starts depending on a cloud repository that was never folded into backup planning. Good maturity here means the business reviews recovery scope as operations change, rather than assuming yesterday’s design still reflects today’s dependency map.
2. Backup resilience checklist
Check that:
- backup credentials are protected separately from production systems
- copies are isolated, immutable, or otherwise hardened against tampering
- storage design reduces the chance of one event affecting all copies
- monitoring exists for failed or incomplete jobs
- backup platforms themselves are reviewed as part of security posture
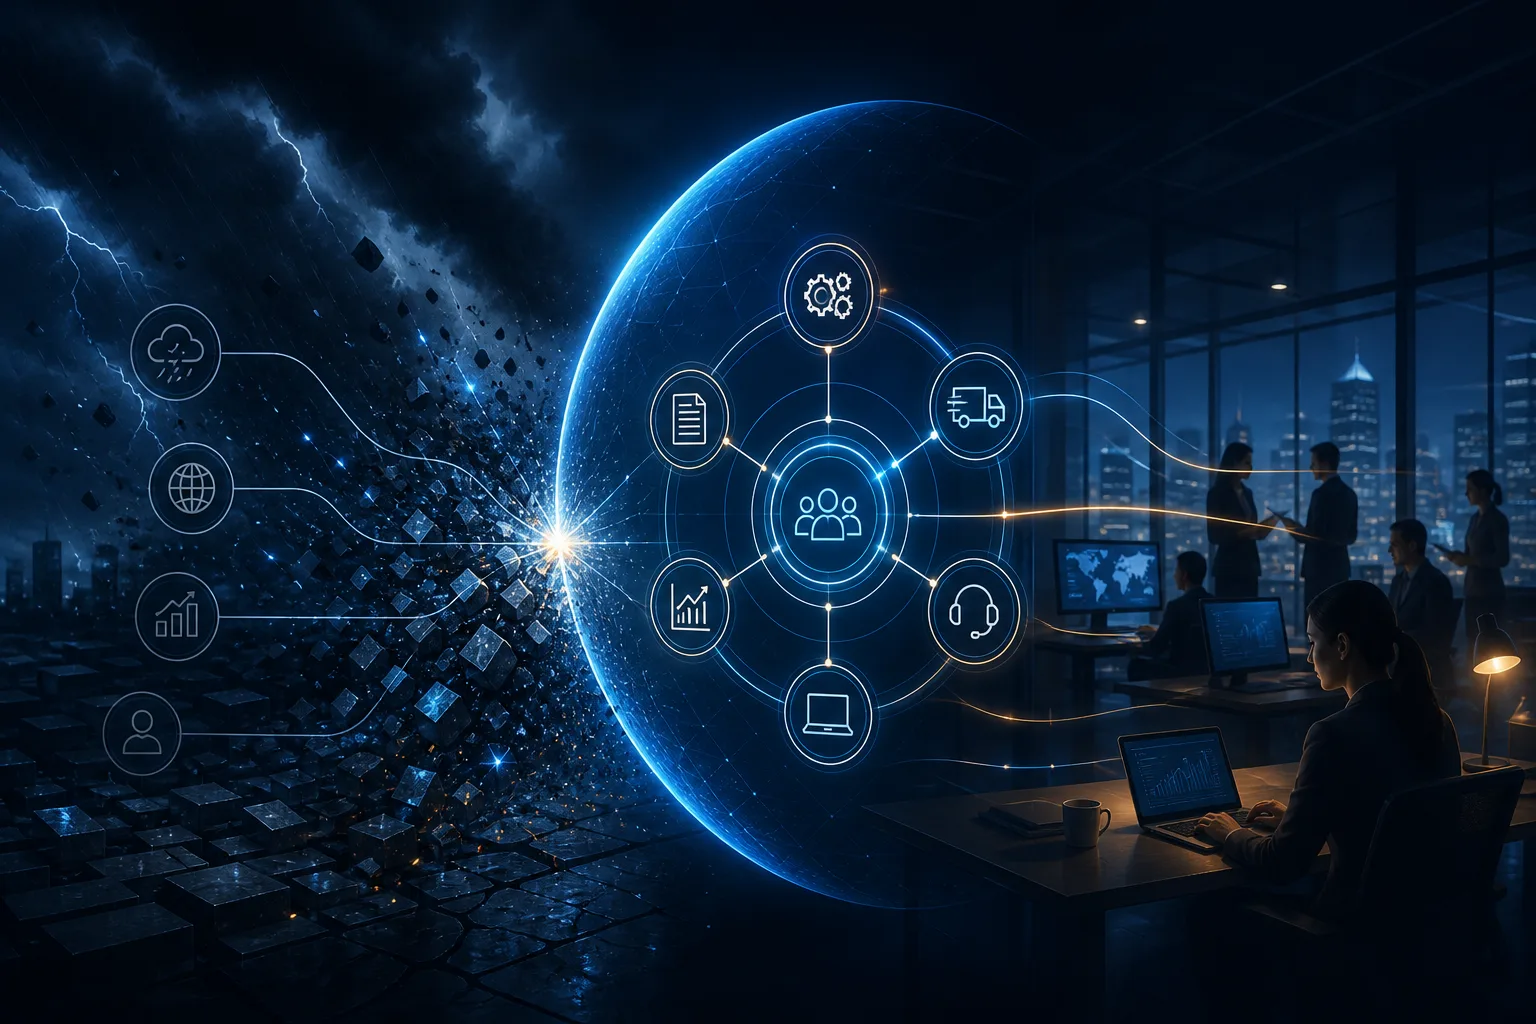
This section matters because ransomware and credential abuse often target recovery capability directly. A backup platform that shares credentials, network paths, or trust assumptions with production systems may be more fragile than it appears. Mature organizations can explain not only that copies exist, but why those copies are likely to remain usable during the kind of disruption that actually matters.
3. Recovery checklist
Confirm whether:
- RTO and RPO are defined and realistic
- restoration tests happen regularly enough to create real confidence
- critical applications can be restored in the right order
- runbooks or documented steps exist for serious recovery scenarios
- recovery ownership is clear before an incident begins
Recovery is where confidence usually breaks down. Jobs may have completed successfully for months, yet the business may have no real proof that critical applications can be restored in the right sequence, within the expected time window, by the people who would actually be responsible during an outage. Strong answers here show that recovery is being treated as an operational discipline, not a theoretical capability.
4. Business continuity checklist
Validate whether:
- business continuity plans exist and are current
- communication responsibilities are defined
- vendor dependencies are understood
- alternate operating methods are documented where needed
- leadership knows how disruption decisions will be made
Backup and DR are necessary, but they do not automatically create continuity. Even a technically successful restoration can still leave the business struggling if communications are unclear, priorities conflict, or decision authority is vague. This is the point where technical recovery and business continuity need to connect.
5. Red flags to watch for
A backup and DR strategy usually needs deeper review when:
- backup success is being used as the main proof of recoverability
- no one can point to recent full restore evidence
- recovery timing is assumed rather than tested
- key business systems depend on undocumented restoration order
- continuity planning lives in scattered documents without ownership
These warning signs matter because they usually indicate deeper maturity issues, not isolated oversights. If no one can produce restore evidence, if recovery timing has never been challenged, or if continuity planning is scattered across vendors and folders, the business is likely relying on optimism more than evidence.
What strong and weak answers usually mean
Strong answers suggest the organization understands the difference between backup success and recovery readiness. They usually include tested restores, clear ownership, documented sequencing, and realistic leadership expectations.
Weak answers suggest the business may be accepting more continuity risk than it realizes. That does not mean recovery would fail. It does mean the organization would probably be forced to make high-stakes decisions without the clarity it expects to have.
What current evidence tells us
Verizon’s 2025 DBIR reported that ransomware was present in 44% of breaches.
That matters because backup and disaster recovery plans are often tested hardest when disruption is deliberate and intended to affect restoration capability itself.
The Canadian Centre for Cyber Security identifies ransomware as the top cybercrime threat to Canada’s critical infrastructure.
That threat-direction guidance reinforces why recovery confidence should be treated as an active business priority, not a background technical assumption.
Uptime Institute found in 2024 that 54% of respondents said their most recent significant outage cost more than $100,000, and 80% believed their most recent serious outage could have been prevented with better management, processes, and configuration.
That supports the same checklist message: recovery quality depends on preparation, discipline, and testing, not just tool presence.
These facts help explain why backup and DR deserve more than pass/fail job status. The business impact of weak recovery planning is often discovered only after disruption has already started.
Frequently asked questions
Final takeaway
The real question is not whether backups exist. It is whether the business can recover in a usable, timely, well-coordinated way.
Move to a Business Resilience Assessment.
If this checklist exposes weak assumptions, move to a Business Resilience Assessment before the next outage forces the answer.